> ## Documentation Index
> Fetch the complete documentation index at: https://docs.rootly.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Responder Checklist
> If you're the one jumping into the incident channel (not the one configuring forms and workflows), this part is for you.
Rootly is here as a tool to help you respond to incidents. Follow these steps from top-down to prepare for when things go wrong.
Already paged and short of time? The [Responder Cheatsheet](/responder-cheatsheet) is the one-page version — commands and emoji shortcuts only, no setup.
## 1. Declare an Incident
Get the incident open and organized in seconds.
1. **Know the help command** — `/rootly help` run in any Slack channel shows every command available. You never need to memorize anything.
2. **Declare with the new-incident command** — `/rootly new` opens the incident form. Fill in title, summary, and severity — the fields you see are configured by your org, and picking a severity kicks off automations behind the scenes.
3. **Use private incidents when it's sensitive** — Security issues, customer escalations, or anything needing tightly controlled access should be declared private. AI features like catchup and summaries still work inside them.
## 2. Work From the Command Center
The incident channel is your home base — everything you need lives there.
1. **Know your command center block** — The pinned message at the top of the channel has the buttons and links you'll use most: paging, updating, resolving, and links out to your team's tools (bridge, ticketing, etc.).
2. **Catch up instantly when you join mid-incident** — Use the catch-up command instead of scrolling the whole channel history.
3. **Ask Rootly for a summary** — Get an AI-suggested summary of the incident so far, and use it as a starting point rather than writing one from scratch.
## 3. Know Your Role and Your Tasks
Roles come with built-in responsibilities — lean on them.
1. **Check what role you've been assigned** — Roles carry default tasks that get created automatically the moment you're assigned, so check your tasks as soon as you join.
2. **Use roles to get oriented fast** — If you're newer to on-call or IR, seeing who holds which role tells you exactly who to go to for what.
3. **Mark tasks done as you go** — Keeps the incident tidy and gives anyone joining later an accurate picture of what's already been handled.
## 4. Update the Incident & Use Emoji Reactions
A couple small habits that save everyone time later.
1. **Add the affected service when you know it** — The moment you attach a service, its runbook attaches automatically and new tasks get created from it — no one has to remember the checklist by hand.
2. **React with the pin emoji on anything retro-worthy** — This is the most important one: pinning builds your retrospective as you go. You can always edit or prune later, but you can't get back a moment nobody flagged.
3. **Know the other emoji shortcuts** — A star can turn a message into a task, and a memo/note emoji can turn one into a follow-up — check with your admin team which emoji are wired up for your org.
## 5. Page, Escalate & Resolve
Bring in the right people, and close it out cleanly.
1. **Use any of the three paging paths** — Ask Rootly who to page, run `/rootly page`, or hit the Escalate button in the command center. All three reach the same on-call rotations, so use whichever is fastest in the moment.
2. **Let severity changes do the notifying** — Updating severity (e.g. to Sev 2) automatically posts to the leadership channel — you don't need to separately ping anyone.
3. **Use the AI assist when you resolve** — The resolution form suggests a summary for you; review and adjust it rather than writing one cold.
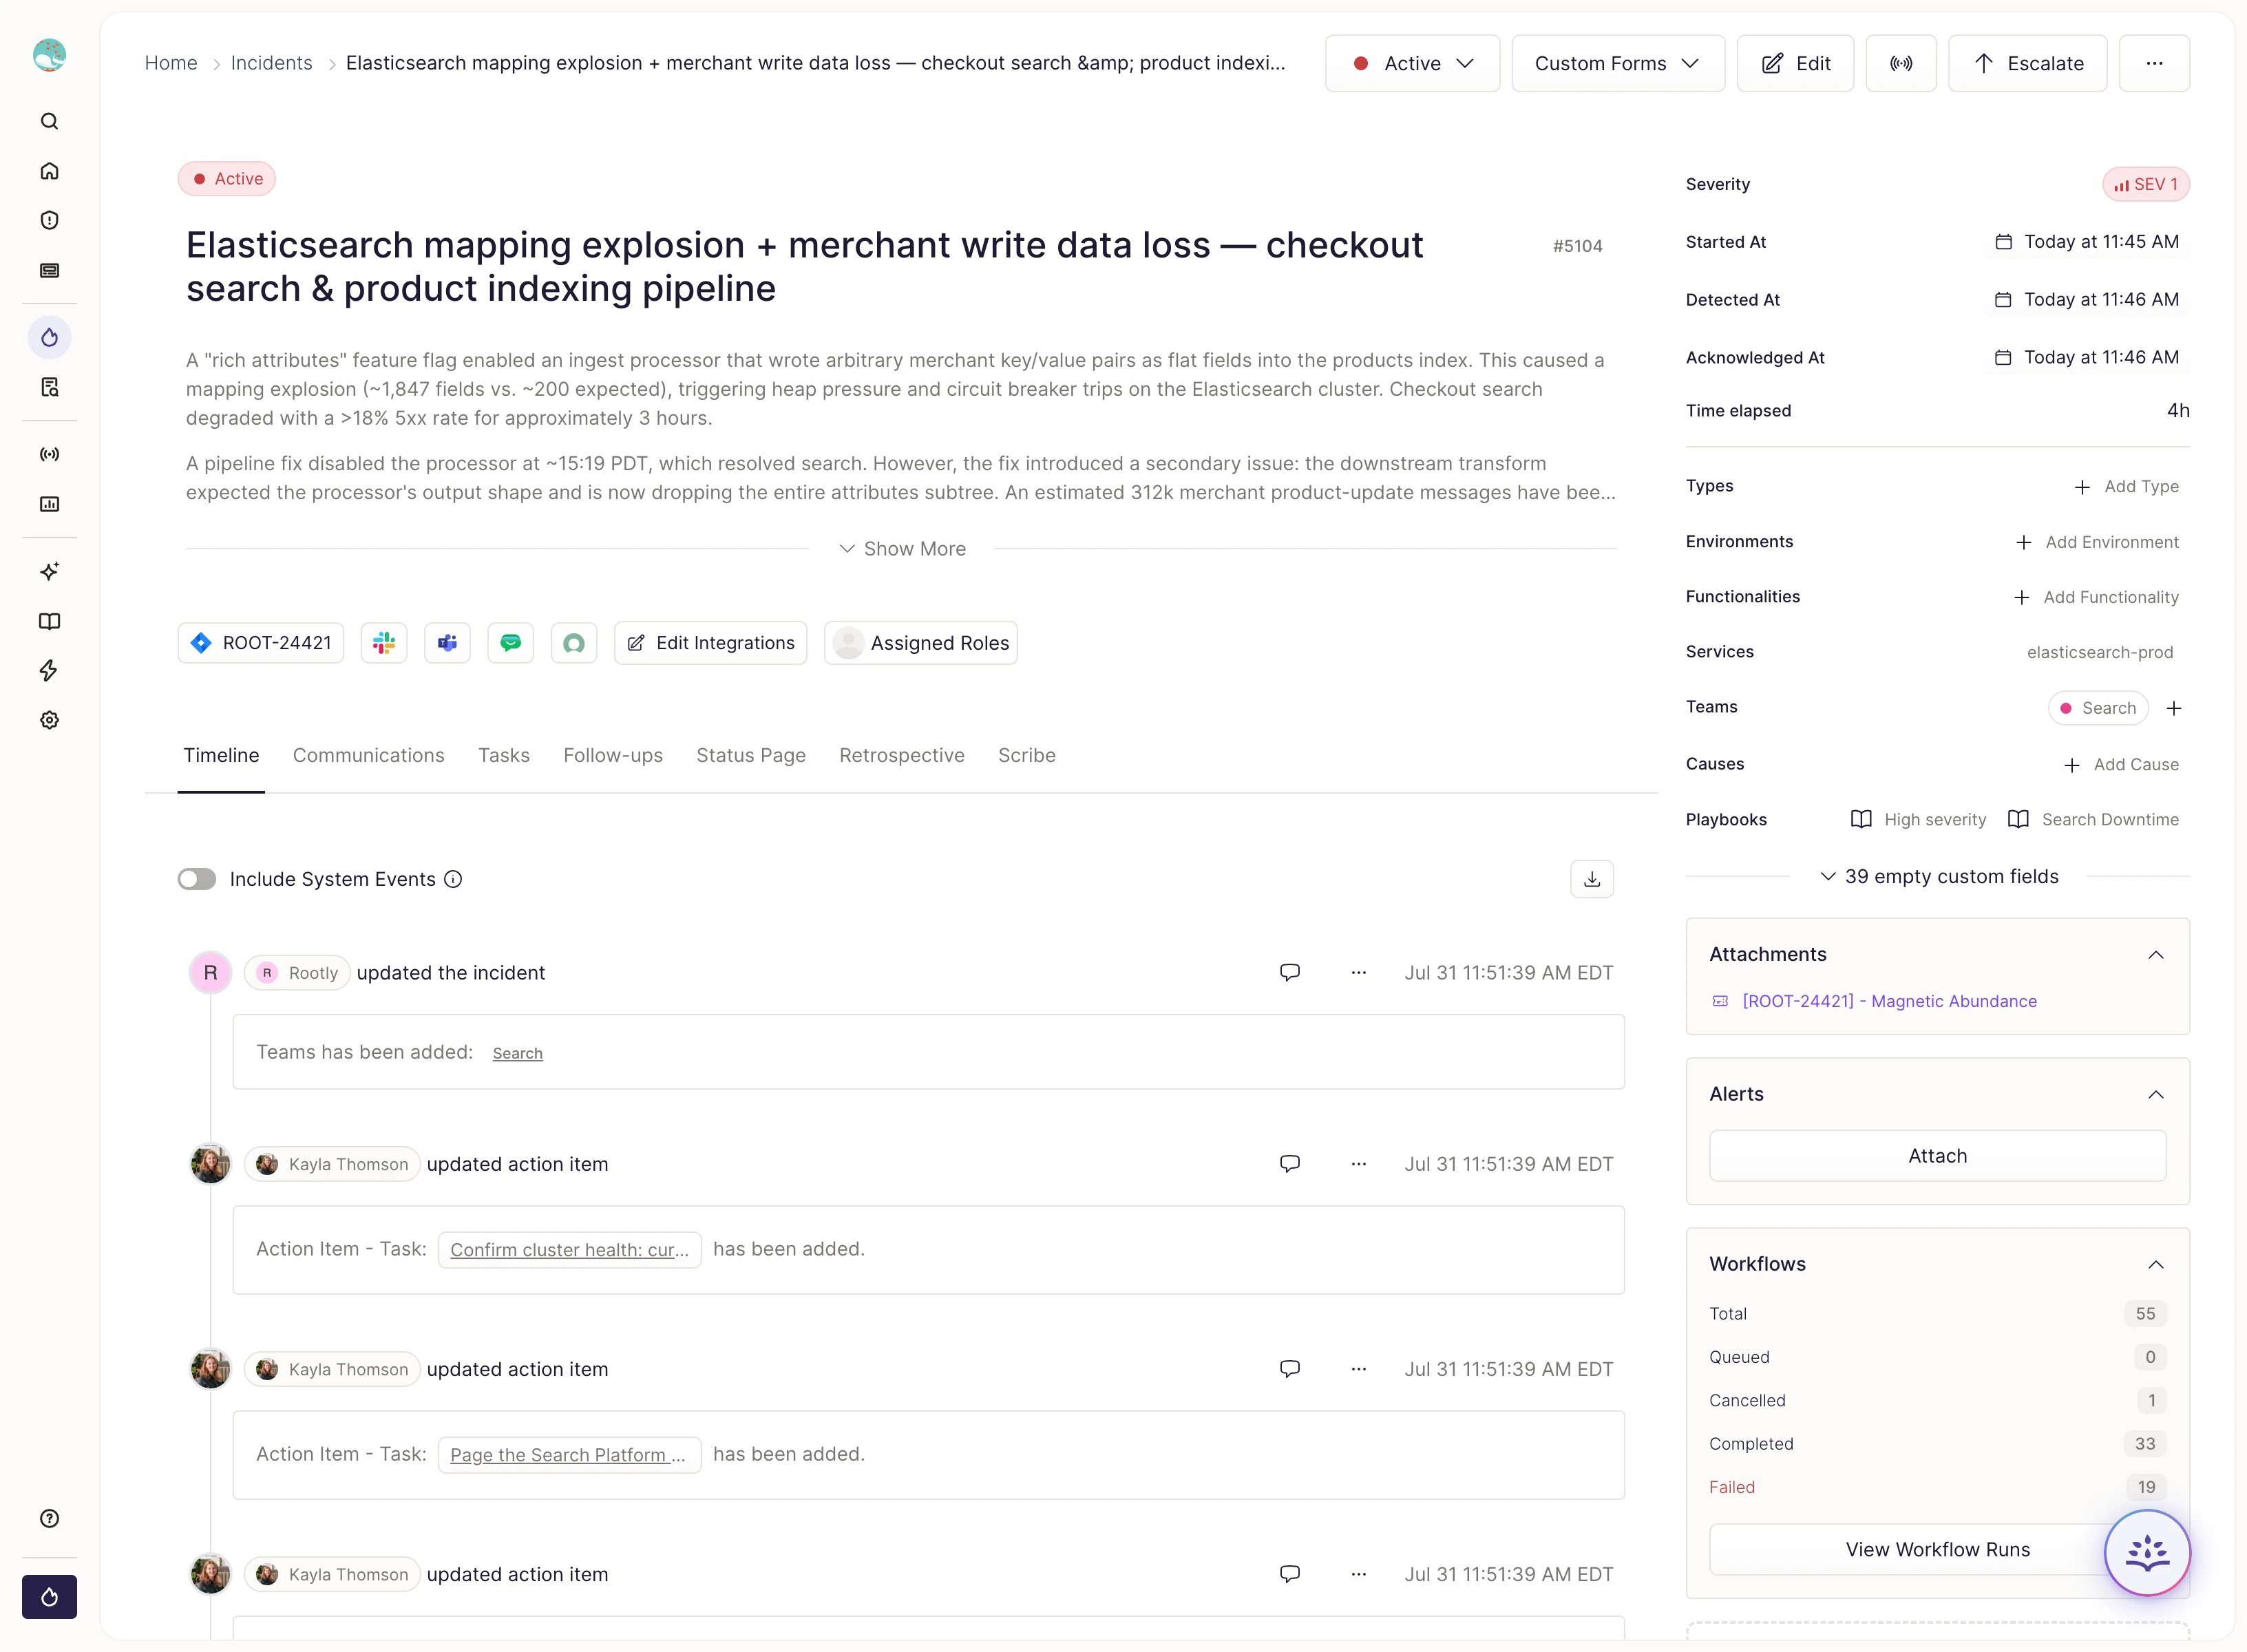
## 6. Know the Web UI Tabs
Everything from Slack also lives here — useful once things slow down.
1. **Timeline** — The fastest way to find your pinned messages and reconstruct what happened, in order.
2. **Tasks** — Broken out by role assignment and by runbook, so you can see what's outstanding at a glance.
3. **Follow-ups** — Shows any auto-created tickets (e.g. Jira) so you can track post-incident work without leaving Rootly.
4. **Status page** — Not automatically in sync with incident status — someone needs to manually publish updates here.
5. **Retro** — Where the retrospective lives once the incident resolves; this is where your pinned messages end up.
6. **Scribe tab** — Reinvite the scribe if it dropped, and pull up the call recording/transcript afterward.
 This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.